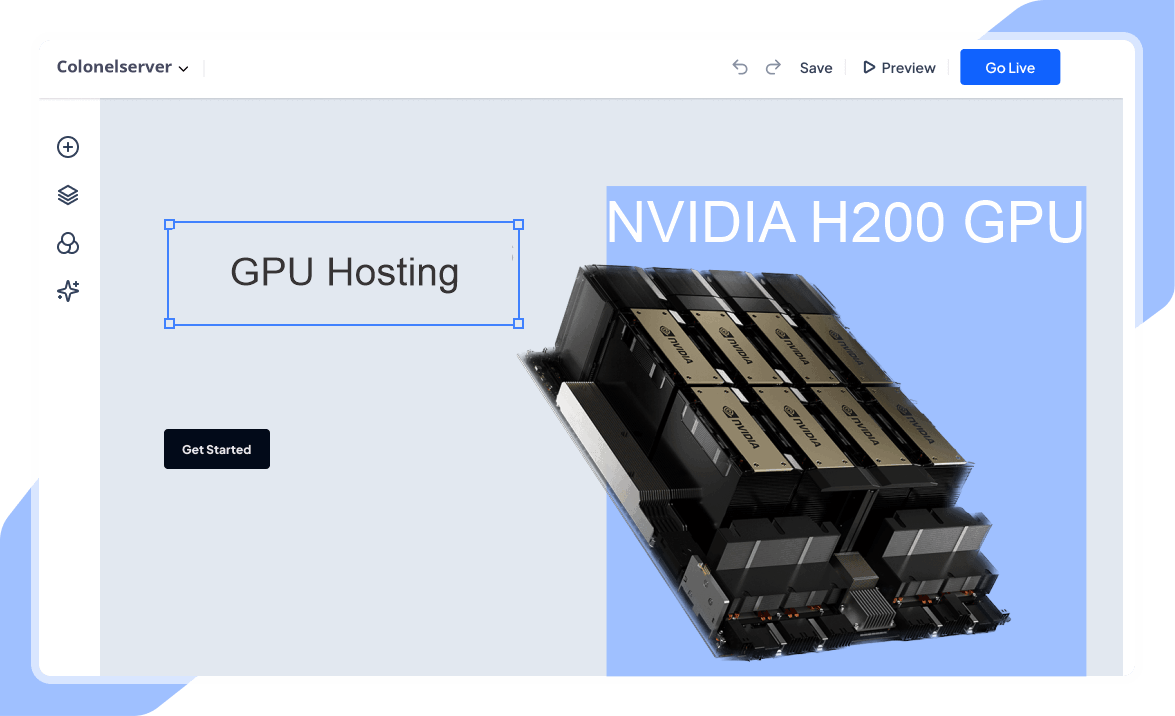
Deploy high-performance NVIDIA H200 GPUs
Run demanding AI workloads on powerful NVIDIA H200 GPUs with fast deployment, high-performance infrastructure, and scalable cloud compute designed for modern machine learning applications.
- Optimized for AI & LLM workloads
- High-performance GPU infrastructure
- Scalable cloud deployment
- Enterprise-grade compute performance
Starting at
€2.30 per GPU / hour

Our Customer Happiness
Colonel is rated on Google Review
Colonel is rated on Capterra
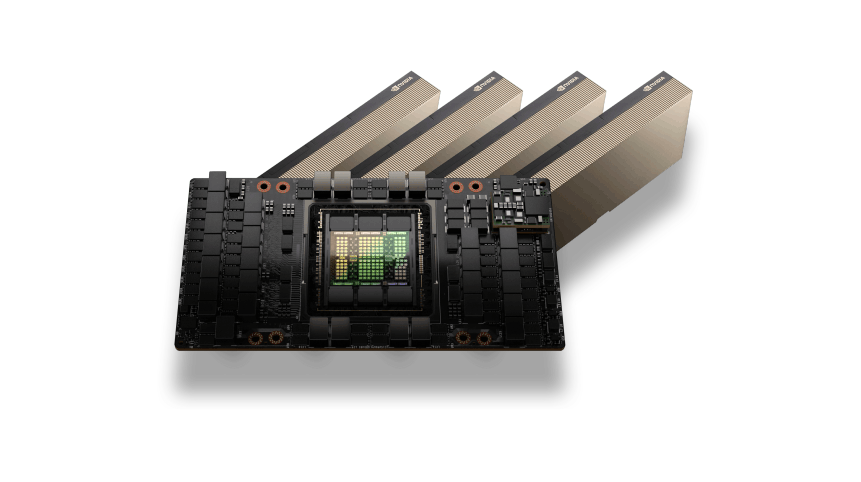
NVIDIA H200 GPU Architecture
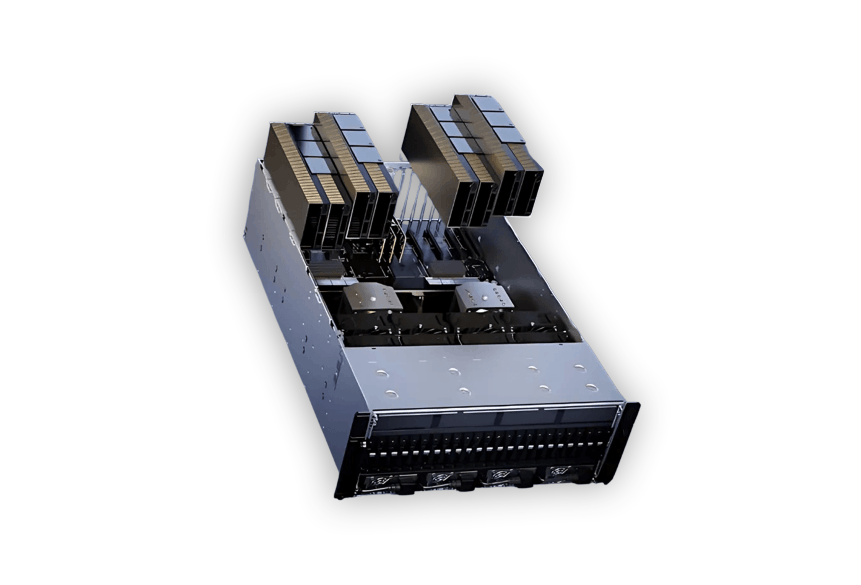
The NVIDIA H200 GPU is built on the Hopper architecture and delivers exceptional performance for modern AI workloads. With massive HBM3e memory capacity and extremely high memory bandwidth, H200 GPUs are designed to handle large language models, deep learning training, and high-performance computing tasks.
AI and HPC Performance
NVIDIA H200 GPUs are optimized for demanding AI and HPC environments where large datasets and complex computations require powerful acceleration.
Whether running AI training pipelines, LLM inference, or scientific simulations, H200 GPUs provide the compute performance needed to process large workloads efficiently while maintaining low latency and high scalability.
NVIDIA H200 GPUs Use Cases
AI Model Training
Train large-scale machine learning and deep learning models using the massive compute power of NVIDIA H200 GPUs. Ideal for training transformer models, neural networks, and large datasets.
LLM Inference
Deploy and run large language models (LLMs) such as GPT-style models, chatbots, and AI assistants with high-performance GPU inference.
High Performance Computing (HPC)
Accelerate scientific simulations, research workloads, and complex computational tasks that require massive parallel processing.
AI Data Processing
Process and analyze large datasets for AI pipelines, including preprocessing, feature extraction, and large-scale data analytics.
Rendering and Simulation
Run GPU-intensive workloads such as 3D rendering, video processing, and physics simulations that require powerful parallel GPU computing.
Flexible H200 GPU Pricing
H200 GPU
Flexible on-demand GPU compute for AI training, inference workloads, and high-performance applications.$2.30 per GPU / hour
Best PriceTop Featured
NVIDIA H200 GPU acceleration
141GB HBM3e GPU memory
Hourly pay-as-you-go billing
High-performance NVMe storage
Fast 10–100Gbps networking
Ideal for AI training and inference
Scalable GPU cloud infrastructure
Deploy within minutes
Optimized for LLM workloads
Enterprise GPU Infrastructure
Need large-scale GPU capacity for AI training clusters or enterprise workloads?$ Custom Pricing
For multi-GPU deployments and dedicated clustersTop Featured
Multi-GPU H200 clusters
Dedicated GPU servers
Custom CPU, RAM, and storage configurations
High-speed GPU networking infrastructure
Designed for AI training and HPC workloads
Enterprise-grade performance and reliability
Scalable AI compute environments
Priority technical support
Enterprise Features of NVIDIA H200 GPU Servers
Extreme AI Training Performance
Leverage the massive compute power of NVIDIA H200 GPUs to train large-scale AI models, deep neural networks, and complex machine learning workloads with exceptional speed and efficiency.
Large HBM3e GPU Memory
H200 GPUs provide high-capacity HBM3e memory designed for demanding AI workloads, large language models, and high-performance data processing pipelines.
Optimized for LLM Workloads
Run modern large language models and AI inference workloads efficiently with GPU architecture optimized for transformer models and generative AI applications.
High-Speed GPU Infrastructure
Our GPU servers are deployed on high-performance infrastructure with NVMe storage and fast networking, ensuring low latency and maximum compute performance.
Scalable GPU Deployment
Easily scale your compute environment from a single GPU instance to multi-GPU workloads depending on your AI training or inference requirements.
Flexible Cloud or Dedicated Deployment
Choose between on-demand cloud GPU instances for flexible workloads or dedicated GPU servers for long-running AI training and enterprise deployments.
Need Help Choosing the Right GPU Infrastructure?
GPU Server Frequently Asked Questions
Find answers to common questions about NVIDIA H200 GPU servers, deployment options, pricing, and AI workload capabilities.

Live Chat
24/7/365 Through the Chat Widget important if you run.
NVIDIA H200 GPU hosting provides accelerated compute for AI, large language models, and memory-intensive applications. Choose a server configuration around your model size and workload.
H200 servers can support deep learning, large-model inference, scientific computing, and other compatible GPU-accelerated applications. Actual performance depends on software and workload configuration.
GPU memory holds model weights and working data. Larger models, bigger batches, and longer contexts increase memory requirements, so estimate these needs before selecting a server.
You can use compatible GPU-enabled frameworks with a suitable NVIDIA driver and CUDA software stack. Check the framework version and deployment image requirements before installation.
No. Smaller models and development tasks may fit other GPU options. Compare memory requirements, measured performance, and running costs to choose suitable hardware.
Review the available GPU configuration, system RAM, CPU, storage, network allowance, and billing terms. Match these resources to your application and expected usage.
Match GPU memory to your model or rendering workload, then allow enough system RAM, CPU, and storage for data preparation and application processes. Test representative workloads before scaling.
GPU-accelerated rendering is possible with compatible software. Confirm support for your GPU model, driver version, operating system, and application licence before deployment.
Yes. Keep independent copies of datasets, code, configuration, and model checkpoints. GPU compute resources do not replace a backup and recovery plan.
Confirm GPU availability, driver and framework compatibility, storage capacity, network terms, and billing conditions. Choose a configuration that fits your workload and test it before production use.