Understanding the Difference Between AI Training and AI Inference
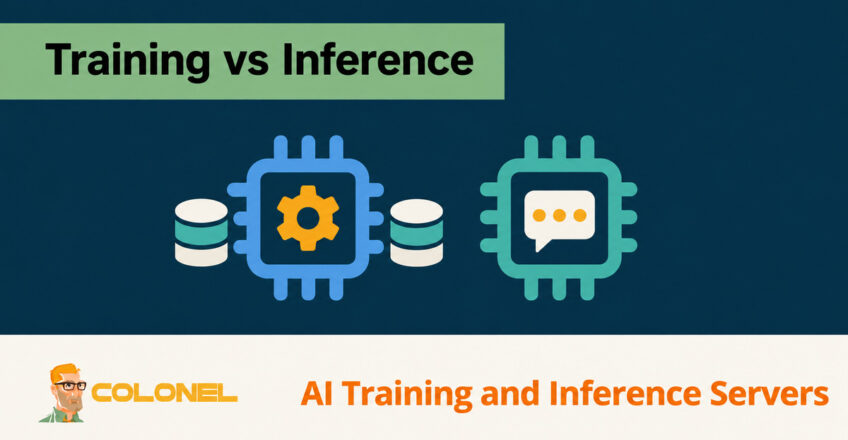
Artificial intelligence workloads generally fall into two categories: training and inference. Although both rely on machine learning models, their infrastructure requirements are significantly different.
Training is the process of teaching a model using large datasets. It requires enormous computational resources, large amounts of memory, and extensive storage capacity.
Inference occurs after training is complete. During inference, the trained model processes new inputs and generates predictions or responses in real time.
Understanding these differences is essential when selecting hardware, designing infrastructure, or choosing GPU hosting solutions.
What Is AI Training?
AI training is the process of building and optimizing machine learning models using large datasets.
During training, the system repeatedly analyzes data, adjusts parameters, and improves prediction accuracy through multiple iterations.
WordPress-Webhosting
Ab 3,99 $/Monat
Beispiele hierfür sind:
- Training großer Sprachmodelle
- Image recognition systems
- Empfehlungsmaschinen
- Fraud detection models
- Speech recognition systems
Training workloads are among the most computationally demanding tasks in modern computing.
Characteristics of AI Training
Training environments typically require:
- Massive GPU resources
- Large memory capacity
- Hochgeschwindigkeitsspeicher
- Long processing times
- Large datasets
Training jobs may run continuously for days or even weeks depending on model complexity.
What Is AI Inference?
AI inference refers to using a trained model to make predictions or generate outputs.
Beispiele hierfür sind:
Günstiger VPS-Server
Ab 2,99 $/Monat
- Chatbot responses
- Image classification
- Product recommendations
- Language translation
- Sprachassistenten
Unlike training, inference focuses on serving requests quickly and efficiently.
Characteristics of AI Inference
Inference environments prioritize:
- Geringe Latenz
- High request throughput
- Efficient resource utilization
- Schnelle Reaktionszeiten
- Skalierbarkeit
Most production AI applications spend far more time performing inference than training.
AI Training vs AI Inference
Ressourcenverbrauch
For the same model and batch, training usually requires more compute and memory because it also calculates gradients and updates parameters. At deployment scale, aggregate inference demand can exceed the resources used for training.
Training workloads involve:
- Forward propagation
- Backpropagation
- Gradient calculations
- Parameter updates
Inference only performs forward-pass calculations.
Windows VPS-Hosting
Fernzugriff und vollständige Verwaltung
Infolge, inference requires substantially less compute power for each request.
Latency Requirements
Training prioritizes throughput rather than immediate responsiveness.
Inference environments often have strict latency requirements.
Zum Beispiel:
- Chatbots may require responses within milliseconds.
- Fraud detection systems may need real-time decisions.
- Recommendation engines must respond instantly.
Storage Requirements
Training infrastructure typically stores:
- Raw datasets
- Processed datasets
- Model checkpoints
- Training logs
- Intermediate outputs
Inference environments primarily store:
- Trained models
- Cached data
- Operational logs
Infrastructure Complexity
Training environments often involve:
- Multi-GPU-Cluster
- Distributed computing frameworks
- High-speed interconnects
Inference infrastructure is generally simpler but requires strong scaling and load-balancing capabilities.
Infrastructure Requirements for AI Training
Training modern machine learning models requires substantial hardware resources.
GPU Selection for AI Training
The GPU is usually the most important component in a training environment.
NVIDIA H100
The H100 is a Hopper-generation accelerator used for demanding training and inference workloads.
Zu den Vorteilen gehören:
- 80 GB HBM3 memory on the H100 SXM variant
- Massive tensor performance
- Exceptional memory bandwidth
- Advanced Transformer Engine support
Ideal workloads include:
- Große Sprachmodelle
- Generative AI
- Deep learning research
- Scientific computing
NVIDIA A100
The A100 remains a highly capable training accelerator.
Zu den Vorteilen gehören:
- Excellent price-to-performance ratio
- Strong multi-GPU scaling
- Mature software ecosystem
Geeignet für:
- Machine learning research
- Enterprise AI
- Data analytics
- Mid-sized training clusters
CPU Requirements for Training
Although GPUs perform most calculations, CPUs remain important for:
- Data preprocessing
- Batch preparation
- Dataset loading
- Task scheduling
Illustrative server configurations may include the following; size CPU resources from measured data-loading and preprocessing demand:
- 16 Zu 64 CPU-Kerne
- Hohe Speicherbandbreite
- Prozessoren der Enterprise-Klasse
Popular choices include:
- AMD EPYC
- Intel Xeon
Memory Requirements for Training
Training environments often require large amounts of RAM.
Recommended capacities include:
- 128 GB RAM as an illustrative server configuration, not a universal minimum
- 256 GB RAM for larger workloads
- 512 GB or more for enterprise deployments
Memory shortages can significantly slow down training performance.
Storage Requirements for Training
Training workloads frequently process terabytes of data.
Recommended storage architecture:
NVMe SSD-Speicher
Verwendet für:
- Active datasets
- Training data
- Model checkpoints
Large-Capacity Storage
Verwendet für:
- Historical datasets
- Archives
- Backup repositories
Fast storage helps eliminate bottlenecks when feeding data to GPUs.
Infrastructure Requirements for AI Inference
Inference workloads focus on delivering predictions quickly and efficiently.
GPU Selection for Inference
Choosing the right GPU depends on model size and latency requirements.
NVIDIA L40S
The L40S is highly effective for:
- Chatbots
- Image generation
- Empfehlungsmaschinen
- Text classification
- Embedding services
Zu den Vorteilen gehören:
- 48 GB GDDR6-Speicher
- Starke Inferenzleistung
- Operating costs that depend on utilization and hosting price
- Workload-dependent performance per unit of cost
NVIDIA H100
The H100 is one option to benchmark for:
- Große Sprachmodelle
- Multi-modal AI
- Ultra-low latency services
- Enterprise AI platforms
Its large memory capacity and bandwidth allow it to handle very large models efficiently.
CPU Requirements for Inference
Inference can be limited by GPU compute, device-memory bandwidth, model capacity or CPU-side request handling. Measure the actual bottleneck before selecting a CPU configuration.
Recommended configurations:
- 16+ CPU threads
- High clock speeds
- Efficient request handling
The CPU supports:
- API processing
- Datenaufbereitung
- Lastausgleich
- Request routing
Memory Requirements for Inference
Inference environments often benefit from:
- 128 GB RAM oder mehr
- In-memory caching
- Multiple model loading
Keeping models in memory reduces loading delays and improves response times.
Storage Requirements for Inference
Inference servers generally require less storage than training environments.
Recommended storage:
- NVMe-SSDs
- Fast local storage
- High IOPS configurations
Storage is used for:
- Model files
- Protokolle
- Cache storage
- Temporary data
Dedicated GPU Servers vs Cloud GPU Instances
Auswerten dedizierte GPU-Server for sustained utilization and Cloud-GPU-Hosting for flexible capacity. Benchmark the same model, batch size and latency target before comparing total costs.
Choosing the right deployment model is just as important as selecting hardware.
Dedizierte GPU-Server
Dedizierte GPU-Server bieten:
- Full GPU access
- Vorhersehbare Leistung
- Complete hardware control
- Consistent monthly pricing
Zu den Vorteilen gehören:
- No shared resources
- Kein Virtualisierungsaufwand
- Better long-term cost efficiency
- Hardware customization options
These benefits make dedicated servers attractive for organizations running continuous AI workloads.
Cloud GPU Instances
Cloud GPU platforms offer:
- Schnelle Bereitstellung
- Skalierung nach Bedarf
- Flexible consumption models
Depending on the selected cloud plan and allocation method, considerations include:
- Resource sharing
- Higher long-term costs
- Vendor lock-in
- Less predictable performance
Cloud infrastructure is often useful for experimentation or temporary projects.
Model Deployment Best Practices
Successful inference environments require more than powerful hardware.
Containerized Deployment
Containers simplify deployment and scalability.
Zu den beliebten Technologien gehören:
- Docker
- Kubernetes
- HashiCorp Nomad
Zu den Vorteilen gehören::
- Portabilität
- Konsistenz
- Einfachere Verwaltung
- Simplified updates
AI Inference Servers
Dedicated model-serving frameworks improve performance.
Zu den beliebten Optionen gehören:
Triton Inference Server
Supports:
- TensorFlow
- PyTorch
- ONNX
- XGBoost
Zu den Funktionen gehören:
- Multi-model serving
- Dynamic batching
- GPU optimization
TorchServe
TorchServe is no longer actively maintained according to its official documentation, with no planned updates or security patches. Do not treat it as a default choice for a new production deployment; assess a maintained serving stack compatible with your model.
TensorFlow Serving
Ideal for production TensorFlow deployments.
Multi-Model Serving Strategies
Many organizations serve multiple models from the same infrastructure.
Zu den Best Practices gehören::
- Keeping frequently used models loaded
- Using lazy loading for infrequently accessed models
- Allocating GPU memory carefully
- Implementing auto-scaling policies
Proper resource management improves both performance and cost efficiency.
Scaling AI Inference Infrastructure
Da der Verkehr zunimmt, inference platforms must scale effectively.
Vertical Scaling
Vertical scaling involves upgrading hardware resources.
Beispiele hierfür sind:
- More powerful GPUs
- Additional memory
- Faster storage
This approach simplifies management but has physical limits.
Horizontal Scaling
Horizontal scaling adds additional servers.
Zu den Vorteilen gehören::
- Improved redundancy
- Greater throughput
- Better fault tolerance
Most large AI platforms rely on horizontal scaling.
Hybrid Scaling
Many organizations combine both approaches.
Beispiele hierfür sind:
- Multiple GPU servers
- Different GPU classes
- Dedicated model clusters
This provides flexibility while maintaining performance.
Security and Monitoring
Production AI environments require strong security controls.
Best Practices für die Sicherheit
Implementieren:
- Firewall-Schutz
- Privates Networking
- API-Authentifizierung
- SSL/TLS encryption
- Zugriffskontrollrichtlinien
Überwachung
Monitor:
- GPU-Auslastung
- CPU-Auslastung
- Speicherverbrauch
- Inference latency
- Throughput
Popular monitoring platforms include:
- Prometheus
- Grafana
- ELK Stack
- Netdata
Visibility into system performance helps prevent outages and performance degradation.
AI Training vs AI Inference: Which Requires More Infrastructure?
Training generally has higher per-batch resource requirements, but production inference capacity depends on traffic, context length, batching and latency targets.
Training environments prioritize:
- Compute power
- GPU-Speicher
- Dataset storage
- Multi-GPU scaling
Inference environments prioritize:
- Geringe Latenz
- Schnelle Reaktionszeiten
- Efficient scaling
- Cost optimization
Organizations building AI infrastructure should carefully separate these workloads and design each environment according to its specific requirements.
Building the Right AI Hosting Environment
Successful AI deployments depend on matching infrastructure to workload requirements. Training environments benefit from powerful accelerators such as NVIDIA H100 or A100 GPUs combined with large memory pools and high-speed storage. Inference environments focus on low-latency response times, efficient scaling, and optimized model serving.
Whether deploying chatbots, Empfehlungssysteme, computer vision applications, or large language models, selecting the correct combination of GPU hardware, server architecture, Lagerung, and networking will directly impact performance, Zuverlässigkeit, and long-term operating costs.